Putting LLM Document Extraction into Production
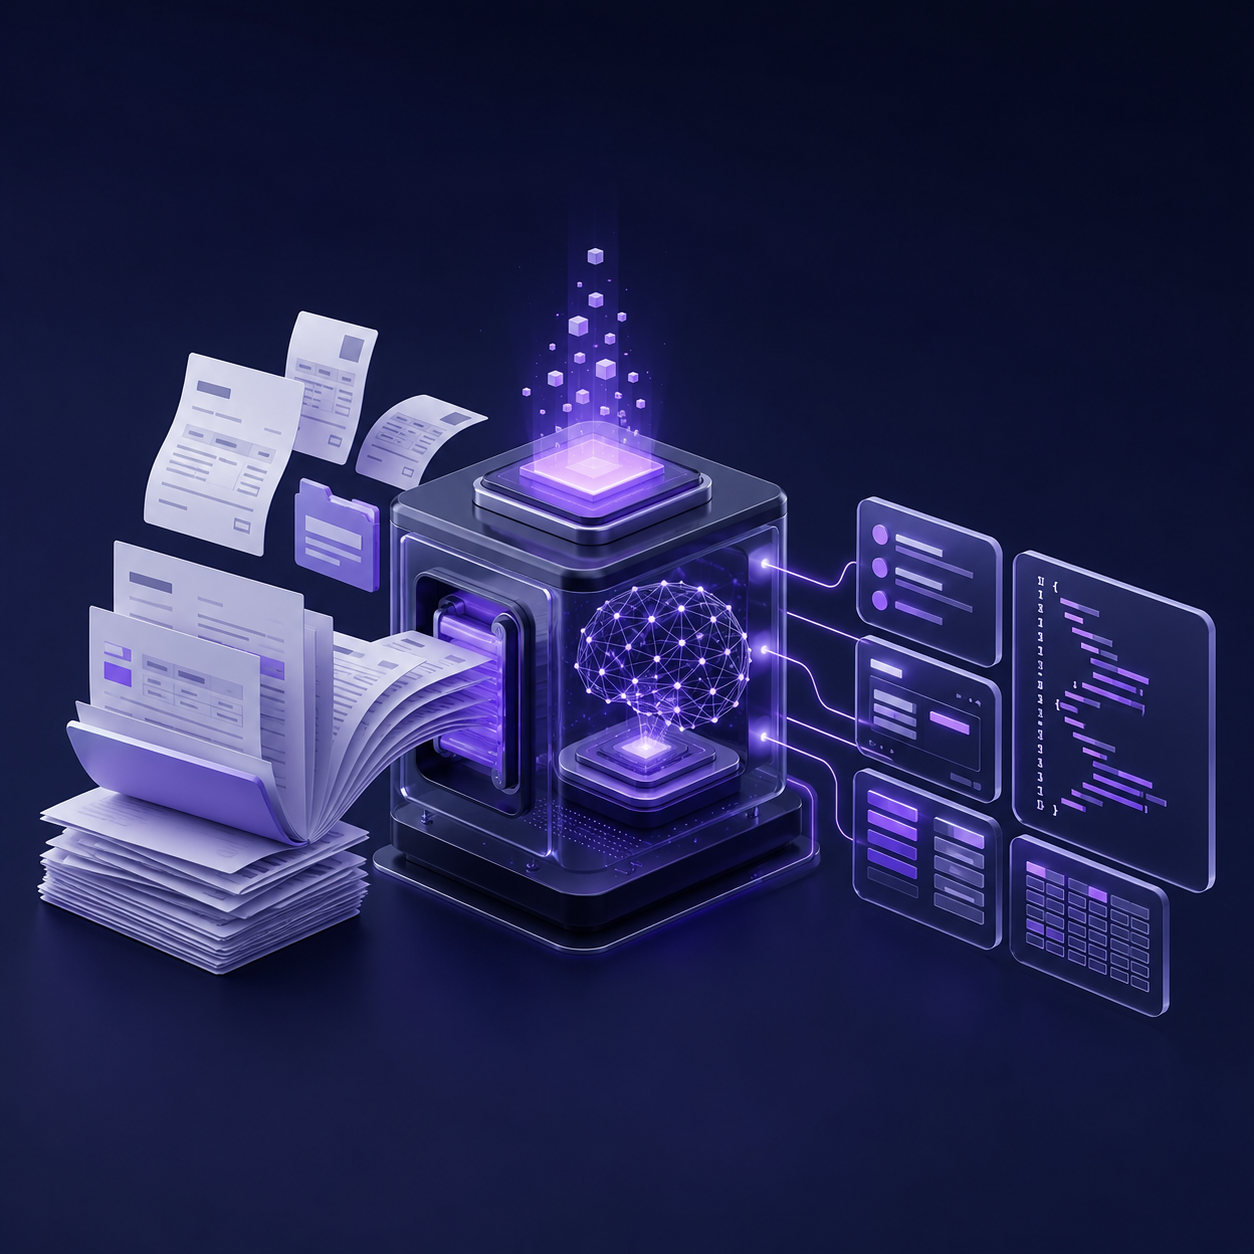
Extracting structured data from a PDF invoice with a large language model looks trivial in a demo. Doing it in production — reliably, auditably, and at a quality a finance team will trust — is a different discipline entirely. These are the lessons I have learned building automated document-intelligence systems.
The gap between a demo and a product
A one-off prompt can pull fields from a clean invoice. But real documents are messy: scans, unusual layouts, missing fields, and figures that have to be correct to the cent. The moment that output feeds a filing or a payment, usually right is not good enough. The system has to be right, and it has to be able to prove it was right.
Extraction is only step one
The model does the reading, but the value is in what comes after. Every extracted field is validated and reconciled against business and legal rules before anything is generated. That validation layer is where trust lives: it turns a probabilistic model into a dependable, auditable workflow.
Architecture you can operate
I build these as small FastAPI microservices over PostgreSQL, with a clean web interface and secure multi-user access. Splitting extraction, validation, and orchestration into separate services keeps each one testable and independently deployable. Everything runs on GCP Cloud Run with Docker, CI/CD, and end-to-end monitoring, so the result is a system you can operate, not just launch.
Make it improve over time
Static models decay as documents change. A continuous fine-tuning loop with LoRA/PEFT lets the extractor keep improving from real usage instead of plateauing on day one. If I had to compress all of it into a single line: in production LLM systems, the model is the easy part — validation, observability, and a feedback loop are what make it hold.